Enough people asked Martin Splitt this question that he brought it to his own boss on a podcast. Working out the answer took the two of them twenty-five minutes, and what they landed on is more useful than the one-line summary that’s been making the rounds.
SEO · Technical
Should You Convert Your Site to Markdown for AI? Google Just Answered.
Google’s Martin Splitt and John Mueller spent 25 minutes on whether sites should ship a Markdown version for AI crawlers. Here is the nuanced answer the headlines flattened.
The line that ended the debate
“For all of the SEO-related things and discovery of content, a normal HTML website is like… the best.”
John Mueller, closing out Search Off the Record episode 111, after twenty-five minutes of genuinely arguing it out with Martin Splitt.
Martin Splitt opened a recent episode of Google’s Search Off the Record podcast with a question he says he gets constantly: should a site convert to Markdown so large language models find it easier to read? He came in with an opinion already formed. By the end, that opinion survived, but picked up a lot of nuance the headline coverage skipped.
The short version that spread across SEO news this week is accurate but flattened: Google says HTML is the standard, Markdown gets you nothing for SEO. True. Also not the most useful part of what was said. The interesting part is why, and where the real exceptions sit.
The argument before the argument
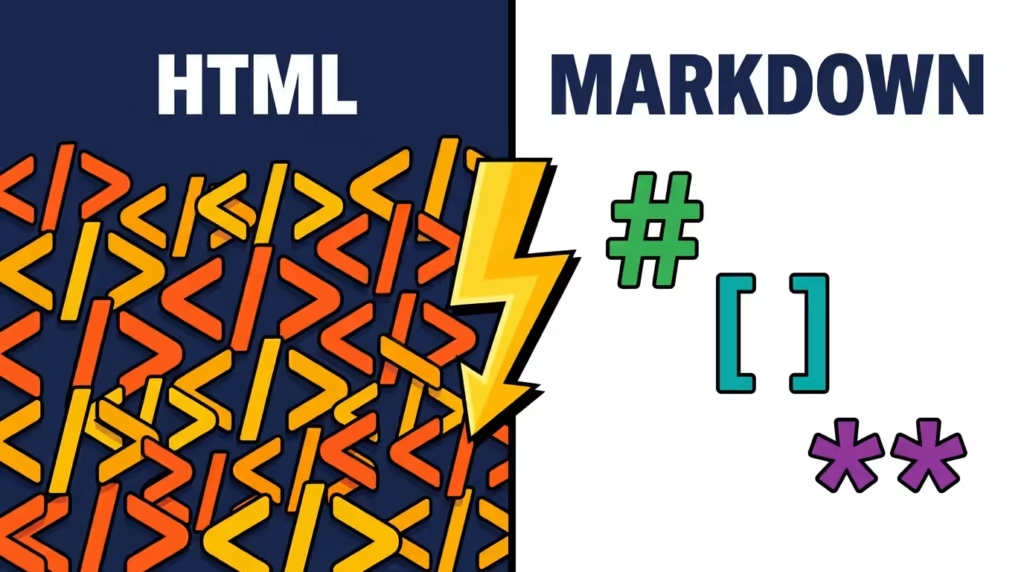
Splitt’s opening case for Markdown was reasonable. It gives you headings, lists, tables, links, and images with a fraction of HTML’s syntax. Harder to get wrong, faster to write, and the structure reads fine with zero rendering. None of that’s in dispute.
His own counterargument is what made the episode worth listening to. Every crawler that exists today already solved the problem of reading HTML at the scale of the entire web. Asking the ecosystem to suddenly prioritize a parallel Markdown version solves a problem that doesn’t exist, the hard problem was solved years ago.
Martin Splitt: All the crawlers that exist today had to deal with HTML for the breadth of ingesting the web. You can’t just say we’re only going to get the Markdown files. So I don’t think that’s a problem that needs solving.
John Mueller: So you know the best practices for making good websites, right? How do you write the content for your site? Do you write HTML or Markdown?
That second line does more work than it looks like. Splitt, it turns out, writes his own personal site entirely in Markdown through a static site generator he built himself, specifically because he doesn’t want to type angle brackets. Mueller used that to pivot the whole conversation: if the advice is “don’t bother with Markdown” but the person giving it writes in Markdown daily, the real answer needs more precision than a flat no.
What Markdown actually is, and why it exists
Mueller dug into the history for the episode. Markdown was created in 2004 by John Gruber and Aaron Swartz, aiming for something close to plain, readable English that converts cleanly to HTML and back. It assumes HTML already exists. It’s not a competitor to HTML, it’s a more pleasant way to author the same eventual output.
Splitt’s framing here is the sharpest technical summary in the episode: Markdown gives you semantic structure almost by accident. A heading is unmistakably a heading. A link is unmistakably a link. Very little room to accidentally make something look like a heading without it being one, a mistake that happens constantly in hand-coded or poorly templated HTML.
The catch Mueller raised
That clean separation only holds if you don’t cheat. Most Markdown processors let you drop raw HTML straight into the file when Markdown can’t express something, embedding a video, a JavaScript widget. The moment you do that, you’ve re-imported all the complexity Markdown was supposed to remove. Used honestly, Markdown forces a clean split between content and presentation. Used as an escape hatch, it’s just HTML with extra steps.
Why "less text" doesn’t mean "better for AI"
The instinct behind wanting a Markdown version for AI is straightforward: open raw HTML in a text editor with nothing rendering it, and it’s genuinely hard to read. Tags everywhere, inline styles, navigation markup tangled into the actual content. Open a Markdown file the same way and it’s still legible, a link still reads as text in brackets followed by a URL in parentheses.
Splitt’s point: that readability gap is real but irrelevant, because no crawler reads raw HTML the way a human squints at a text file. Converting HTML to plain text is a solved, trivial problem with mature tooling everywhere. Markdown’s supposed advantage, easier text extraction, stopped mattering once HTML-to-text extraction became a commodity.
There’s a second, quieter cost the conversation kept circling back to. Markdown by design strips out everything around the content, headers, footers, sidebars, the navigation that tells a crawler how a page connects to the rest of the site. Mueller’s point: for a search engine specifically, those structural links aren’t noise to remove. They’re how Discovery works. A clean Markdown excerpt of an article with the site architecture stripped away is, from a crawling standpoint, a worse signal than the messy HTML it came from.
The llms.txt question, settled pretty bluntly
Splitt asked the natural follow-up: if not a full Markdown site, what about an llms.txt file, a plain text summary aimed specifically at language models? Mueller had spoken directly with one of the people behind the original proposal, and his read on its intended purpose was clear.
The file was never meant as a discovery mechanism, a way to get found by AI systems that haven’t encountered the site yet. It was built for a narrower case: an AI agent that already knows about a site and a user, wanting a structured way to look around once it’s already there.
John Mueller: You’re basically telling these systems, I have the best website ever, and here are all the pages everyone must go to, and you must buy all of my products. An LLM system, by design, can’t trust that as a way of differentiating between websites.
That’s the core problem with treating any self-authored file as an AI optimization lever. A file you control, describing how great your own site is, isn’t a credibility signal to a system trying to figure out which site actually answers a query best. It’s closer to a sales pitch the system has every reason to discount.
Where the exception genuinely lives
Neither of them dismissed Markdown outright, and this is the part most secondary coverage compressed into a footnote. Developer documentation is the one category where both agreed a Markdown version earns its keep, the audience is frequently a developer or coding agent already working in Markdown natively, and it benefits from getting the raw syntax directly.
Earns its place
API references, dev docs, code-heavy technical content generated from the same source as the HTML
Adds nothing
Product pages, service pages, blog content, anything aimed at general search discovery
Mueller’s closing line was blunt: if you’re selling shoes, you’re not going to have a Markdown version of your shoe catalogue. He put the temptation down to developer bias, the assumption that because developers personally find Markdown easier, every site must benefit from the same approach. Most websites aren’t run by developers alone, and most content isn’t documentation.
The parallel-versions problem nobody budgets for
The strongest practical warning in the episode had nothing to do with crawlers and everything to do with maintenance. The moment a site runs two versions of its content, a public HTML version and a separate Markdown or JSON version for automated systems, it’s taken on a maintenance burden that compounds quietly.
- If the human-facing page breaks, a user notices and tells you. If the automated-only version breaks, nobody does, and a crawler may keep indexing stale or broken content indefinitely with no signal reaching you.
- Every content update now needs to happen in two places, or through a pipeline that keeps them in sync. That pipeline is itself a new point of failure that didn’t exist when there was one version of the truth.
- Both Splitt and Mueller compared this directly to dynamic rendering, an earlier-generation workaround where sites served crawlers a different version of a page than users saw. It worked as a stopgap, then became a maintenance and debugging burden once sites depended on it long term. A parallel Markdown layer risks the same trajectory.
- The cleanest answer to wanting both formats is generating one from the other through a single pipeline rather than maintaining two sources by hand, the same approach Splitt already uses for his own site with its static-site-generator setup.
What this means if you run a website
If someone’s asked whether converting the site to Markdown, or standing up an llms.txt file, would help AI visibility or search performance, the answer from the people who build Google’s crawling and indexing systems is consistent and specific. Clean, well-structured HTML with proper headings, working internal links, and clear semantic markup remains the entire foundation. Nothing about the rise of AI search changes that, because those systems are still built on the same HTML-parsing infrastructure search engines have used for decades.
Where the conversation has genuine room to add value is for sites with substantial developer-facing content, where a real Markdown layer generated from the same source as the HTML can serve coding agents and human developers without creating a second source of truth. For everyone else, including most commercial sites doing generative engine optimization work, the energy is better spent on the boring fundamentals: structured data, clean semantic HTML, and a site architecture a crawler can actually navigate.
The honest summary
Markdown is a genuinely good authoring format. It’s not an SEO format, and it never claimed to be one. The confusion comes from conflating “easier for a human to write” with “more discoverable by a machine,” unrelated properties. If your content workflow is easier in Markdown, keep using it, and generate clean HTML from it as the single source of truth. If someone tells you to publish a parallel Markdown version of your product pages for AI search, that advice doesn’t hold up against what the people building these systems actually said.
Want AI visibility built into a full growth system?
We will show you exactly where this fits alongside the rest of your marketing.